For Data & Business Leaders Download Our Free Ebook
  • Home
  • /
  • Solution
  • /
  • Data Reconciliation & Audit Trail Solution Accelerator

Solution Accelerator

Data Engineering

Spark / Databricks

RowHash Utility Accelerator

Reference utility, reusable notebook logic, and implementation guidance to generate deterministic row-level hashes for Spark DataFrames and use them to drive SCD Type 2 incremental loads, change detection, deduplication, and reconciliation workflows.

Language

Python

Deployment

Databricks Notebook / Workflow

Type

Reusable Utility + Guide

Trusted By :

How it works

Detect row changes without comparing every column manually

Incremental data pipelines often need to identify which records have changed between a source batch and a target table. Comparing every column one by one can become complex, expensive, and difficult to maintain as table structures grow.

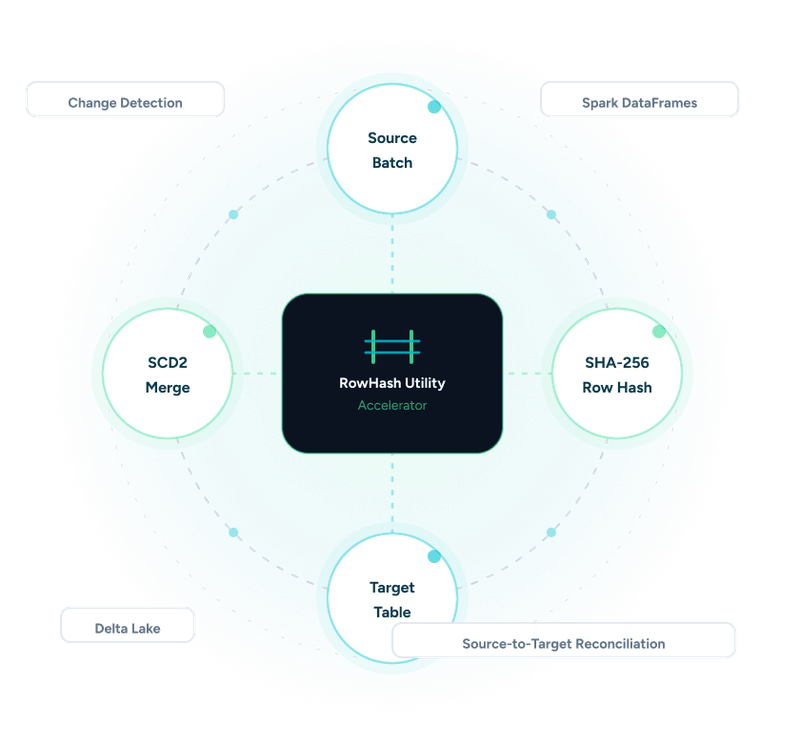
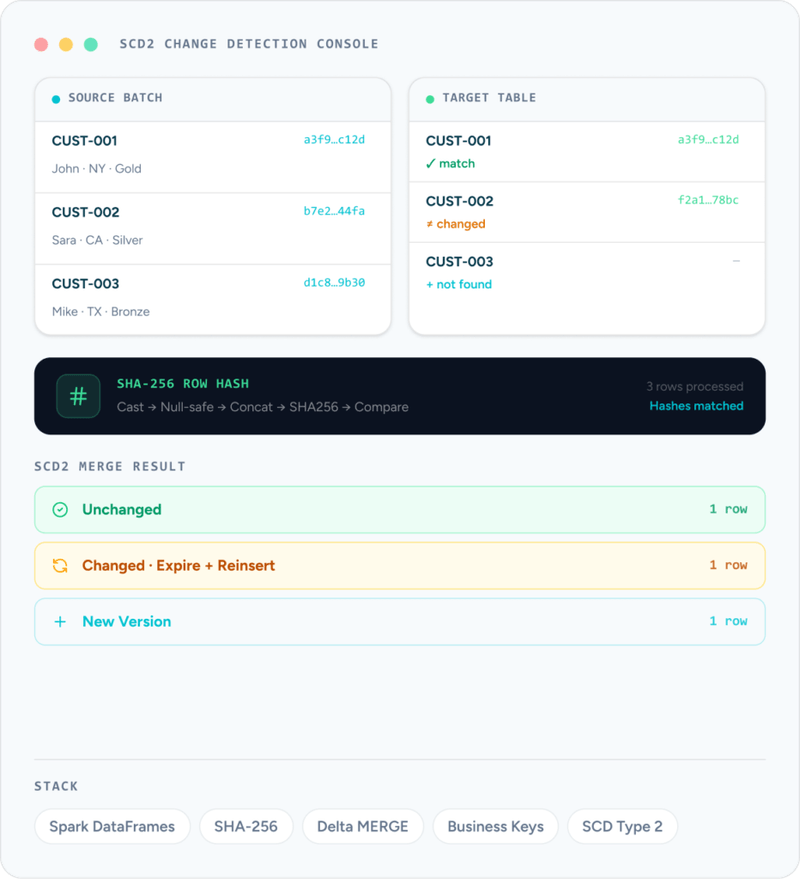
DataTheta’s RowHash Utility Accelerator provides a reusable Spark and Databricks function that converts selected row values into a deterministic SHA-256 hash. That hash represents the business state of each row and can be used to power SCD Type 2 loads, deduplication, and source-to-target reconciliation.

  • Generate a deterministic row hash by casting included columns to string, replacing nulls with empty values, concatenating the selected columns, and applying SHA-256.
  • Exclude audit, technical, timestamp, surrogate key, or business key columns from the hash when they should not define the row’s business state.
  • Compare source and target row hashes to identify changed records more efficiently than comparing every column individually.
  • Use the included SCD Type 2 notebook to expire changed current rows and insert new or updated versions into a Delta target table.
AI systems in production
0 +
Avg. time to first outcome
0 Weeks
Forecast accuracy
0 %
Faster decision cycles
0 X
Revenue influenced by AI
$ 0 M+
Manual processing eliminated
0 %

40+

AI systems in production

8 Weeks

Avg. time to first outcome

34%

Forecast accuracy improvement

3×

Faster decision cycles

$180M+

Revenue influenced by AI

68%

Manual processing eliminated

How it works

What this accelerator helps you do

Deterministic Row Hashing

Create one repeatable SHA-256 hash column that represents the selected business-state columns in each Spark DataFrame row.

Type-Agnostic Comparison

Cast included columns to string and handle nulls consistently so different Spark data types can be compared through one standard hash value.

SCD Type 2 Change Detection

Use source and target row-hash comparison to detect changed records and drive Delta MERGE logic for SCD Type 2 loads.

Reusable Configuration

Keep table names, business keys, sample file names, and display settings in a configuration file so the accelerator can be adapted without rewriting core notebook logic.

Incremental Load Testing

Run a repeatable demo with an initial customer load and an incremental batch containing unchanged, changed, and brand-new records.

Solution Accelerators

Build more reliable data engineering patterns with DataTheta Solution Accelerators.

Explore reusable accelerators for incremental loading, data quality, workflow monitoring, governance, reconciliation, and production-ready data engineering workflows.

Ready to simplify SCD Type 2 change detection?

Use DataTheta’s RowHash Utility Accelerator to generate deterministic row hashes, identify changed records faster, and build cleaner incremental load patterns in Spark, Databricks, and Delta Lake.

©2026 Copyright DataTheta – Lance Labs Inc.

Tell Us What You Need

We’ll use these details only to respond to your enquiry.

No spam. Your information stays private.