Planning Your Enterprise AI Investments? Discover How to Choose the Right AI Use Case →

DevOps

AIOps Reduces Alert Noise
Blog, DevOps

How AIOps Reduces Alert Noise and Improves Incident Response

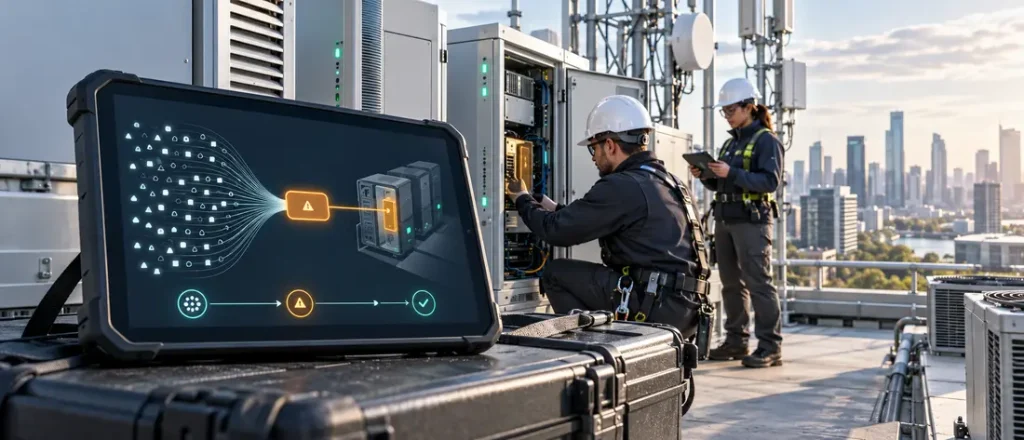
Introduction A modern IT infrastructure generates tons of data, a constant stream of logs, various metrics, events, and alerts any human resource can keep an eye on by themselves.   Applications, cloud platforms, microservices, databases, APIs, and infrastructure components all produce signals that operations teams need to interpret. The problem is not with the quantity but the quality of signals. It is to find out which information actually matters. A single technical problem can trigger alerts across several connected systems, leaving engineers to investigate multiple stages of the database before they reach the actual cause. For CIOs, this creates a capacity problem. Skilled engineers spend too much time searching for correct alerts and reacting to repetitive incidents, while important issues still get missed and reach the customers. AIOps helps reduce that burden by making operational data easier to interpret, finding the source of problematic data, giving detailed analysis, and suggesting possible solutions. It lowers the need for manual work by automating repetitive tasks, improves incident response through automated monitoring, and enhances operational workflow.  Alert Overload Has Become a Capacity Problem IT infrastructure has various platforms that need a clear alert system to prevent any security and operational issues. One infrastructural problem might generate warnings from an application, database, API, and cloud service at the same time. Finding the correct one independently can end up investigating the same underlying problem several times. Over time, this creates alert fatigue. That is why important signals get buried under several low-value notifications and engineers spend valuable time deciding which one deserves more attention before they can begin solving the actual issue. The Alert overload becomes a capacity problem because of the human effort needed to understand the real issue. Operations teams need a way to separate meaningful incidents from routine noise without relying entirely on manual triage.  What AIOps Actually Does with All That Noise AIOps applies artificial intelligence and machine learning to operational data and has the capabilities of event correlation. It analyses events, looks at the timing of issue appearance, checks affected services, dependencies, historical patterns, and shared symptoms to identify which events are probably connected. This helps in turning a large volume of notifications into smaller numbers of incidents that actually require investigation.   AIOps can also support anomaly detection by identifying unusual behavior before it becomes a larger issue. It analyses root-cause and helps engineers to work on the main problem immediately, saving time from searching manually. Predictable incidents like inventory shortages, machine malfunctions, and routine issues can be automated and can take approved actions without requiring an engineer to perform every step manually. The purpose of AlOps is to reduce the manual work required to understand what is happening and decide what should happen next.  How AIOps Reduces MTTR and Frees Engineering Capacity Mean time to resolution, or MTTR, measures how long it takes to restore normal operations after an incident. And, integrating ALops in an operational environment improves incident responses. When engineers have to differentiate between unrelated or duplicated alerts from large numbers before they find the real issue, the resolution takes longer. AlOps can shorten that process by connecting related events and identifying the cause behind it.    A Forrester Total Economic Impact study of Cortex XSIAM reported a 60% reduction in investigation and remediation time during the first year of deployment. The finding relates to that specific implementation, but it shows what better correlation and automation can make possible. So, it gives plenty of time to engineers to focus more on reliability improvements, automation, platform engineering, and other work that supports the business rather than spending more time on repeatedly investigating the same kind of incidents. As Gartner has put it: “There is no future of IT operations that does not include AIOps.” AIOps Needs Reliable Observability Data AlOps works accurately when it has reliable operational data. The data it needs should be clear, organized, and governed to process correct results. Logs, metrics, traces, events, topology information, and historical incidents provide the context needed to understand how systems behave and where problems may be occurring. If these data are fragmented, duplicated, or incomplete, the system may struggle to distinguish genuine incidents from normal behavior. That is why observability is an important foundation for AIOps.  It gives teams and AI systems a clear view of the problems, their root cause and changes across the environment and how different services are connected to each other. Observability gives AIOps visibility to analyse reliable historical and real-time telemetry with enough context to identify meaningful patterns and approach any problem. Related Posts: – Alternatives to GetOnData for Data Analytics Services Top Data Analytics Companies in Coimbatore for Data Analytics, BI & Reporting Services Automation Should Grow with Trust Organizations need to make sure the data underlying the AlOps are reliable and governed before they gradually extend AlOps into automation remediation. Routine and well-understood incidents are a sensible place to start. If a known condition has a tested response, the system may be able to carry out that action automatically without requiring an engineer every time. But high-risk action still needs stronger controls. Engineers should understand change in any recommendation, system behaving differently, and missed automated alerts, and be able to trace it back to the relevant evidence. Human approval should remain part of the process when an automated action could have a significant impact. Start With Alert Reduction Before Expanding Automation Organizations do not need to make their entire IT environment autonomous from the beginning. They should start where the operational burden is visible and repetitive works are handled manually. Bring logs, metrics, and traces into a more consistent observability environment and identify where duplicate alerts or repetitive incidents consume the most time. Then they should integrate AlOps into the operational environment to improve event correlation and incident triage. And check whether alert volume lowered, MTTR improved, and fewer incidents required manual investigation. Once teams trust the system and see measurable results, automation can be expanded in other areas of workflow. The goal
dataops foundation and mlops, aiops
Blog, DevOps

How DataOps Creates the Foundation for MLOps and AIOps

Introduction There is a hierarchy in Ops disciplines that needs to be kept in view when any organization wants to introduce AI models or features into its operational workflow. It isn’t popular enough to receive consideration from a wider perspective, but it is still important to keep it in view across every operational function. Where AIOps helps IT teams detect and respond to incidents, analyse the root cause of a problem, and suggest possible solutions, MLOps helps teams deploy, monitor, and maintain machine learning models. Both may sound like separate disciplines, but they have one thing in common: they depend on data.  If the data underlying is fragmented, incomplete, wrong or reaches the system late, the system built on that will never give the result any business demands. An AIOps platform working with inconsistent telemetry may connect the wrong events. An ML model receiving unreliable inputs may gradually lose accuracy. That is why DataOps become important. Instead of seeing DataOps, MLOps, and AIOps as three parallel practices, it makes more sense to think of them as connected layers.  What DataOps Actually Does DataOps is a software engineering discipline that uses automated and collaborative practices to build and operate data pipelines. The process includes automated testing, version control, monitoring, observability, quality checks, and controlled changes to pipelines. It transforms, loads data, delivers data continuously, and uses iterative cycles to build and update data workflows. Furthermore, it identifies the data problems as early as possible automatically instead of discovering them days later when they have already affected reports, models, or business systems. If a change happens in an upstream source, without proper controls, that change may flow silently through the pipeline and affect downstream datasets. Teams may realise that something went wrong but much later, when a dashboard looks unusual or an AI model behaves differently. But, with DataOps best practices in operations, automated tests can catch the change closer to the source and stop it from travelling further. That one change can save engineering teams from spending hours tracing problems backwards through systems later. Related posts: – What Is Data Science? Scope, Models, Lifecycle, and Industry Applications Top 10 Data Analytics Companies in Chandigarh for BI, AI & Data Engineering Services Why Reliable Data Improves Both MLOps and AIOps MLOps and AIOps work on different problems. One focuses on the machine learning lifecycle and helps teams to manage model tanning, deployment, monitoring, versioning, and evaluate performance over time. Another is used in IT operations. It uses AI to help analyse, identify anomalies, correlate events, analyse incidents, and automate suitable responses. But neither operates alone. They need a data discipline to maintain accuracy throughout the process.          A machine learning model depends on the quality of the data used to train and update it. If the pipeline starts delivering incomplete or inconsistent information, the model can begin producing poorer results. The same applies to AIOps. It depends on logs, metrics, traces, events, and other operational signals. If those inputs are inconsistent or incomplete, the platform has the wrong database to analyse, operate and identify patterns or find the actual source of a problem. Therefore, a reliable pipeline improves the deliverable result condition for both disciplines in different ways. Giving teams a strong data foundation to work with.     “DataOps doesn’t just help the data team; it raises the ceiling for every Ops discipline above it.” DataOps Makes Governance Part of the Pipeline DataOps makes governance an important part of pipelines. In many organizations, governance still needs manual control. Teams still document where data came from, check quality manually, or prepare evidence when an audit happens. With DataOps in work streamline, it can move some of those controls into the pipelines itself. Lineage can track where data came from and how it changed and a defined quality rules can run automatically. Standard controls can be applied consistently instead of depending on someone remembering to check them.  That makes governance more accessible and practical to apply because it becomes a part of everyday data handling.        For a CDO, the benefit is not only compliance. It also improves confidence. Teams have a clearer way to understand where information came from, whether it passed quality checks, and what happened to it before it reached a model or application. Sequence DataOps Before Expanding MLOps and AIOps If organizations are trying to invest in an AI integrated work place, then all three disciplines should be in sequence. It may be a mistake to treat DataOps, MLOps, and AIOps as three independent tool purchases. A model monitoring system cannot work accurately for constant incomplete information, and AIOps platform cannot consistently identify the right incident when the underlying telemetry cannot be trusted. That is why the relationship between the three disciplines should be taken as layering of a whole system. So, a better approach is to strengthen the data layer first. And add rest after making sure everything related to reliable data is in place. “DataOps makes the data trustworthy, MLOps keeps the models honest, AIOps keeps the systems healthy.”  Related Posts: – What Is Data Analytics? Types, Use Cases, and Real-World Examples Snowflake Database: An Effective Cloud-Native Data Warehousing Platform Conclusion Organizations shouldn’t treat DataOps, MLOps, and AIOps as different disciplines. These three disciplines are equally important and need to function together, even if they solve different operational problems. They are connected by the data moving through them. MLOps alone cannot keep models reliable if the data underneath are unstable and untrustworthy. As same, AIOps cannot identify operational patterns accurately if the telemetry it receives is inconsistent. That is why DataOps should be treated as more than a supporting data engineering practice. DataOps creates discipline in data handling and functioning. It creates the reliability, visibility, and governance that the other disciplines need to work effectively.  A better practice any organization can use is to start with straightening the data layer first. They may begin with a reliable pipeline that includes automated testing, improving observability with Standardise

©2026 Copyright DataTheta – Lance Labs Inc.

Let's Build Your Next Data & AI Solution

Tell us about your business goals, data challenges, or technology requirements. Our team will review your enquiry and connect with you to discuss the right solution.

No spam. Your information stays private.