

Introduction
As the world moves towards AI automation, business intelligence-integrated workflows, and advanced machine learning models, the risks of data breaches, security threats, fraud, and poor governance have also increased. Organizations, government institutions, and healthcare firms generate large amounts of data and store it for further use to improve customer experiences.
Businesses handle payments, banking transactions, insurance claims, account activity, and digital commerce. In doing so, they need security and fraud detection to protect business data. They frequently have to assess these procedures as they are taking place. The system must comprehend the current transaction, assess potential risks, compare it to previous behavior, and determine what further needs to be done.
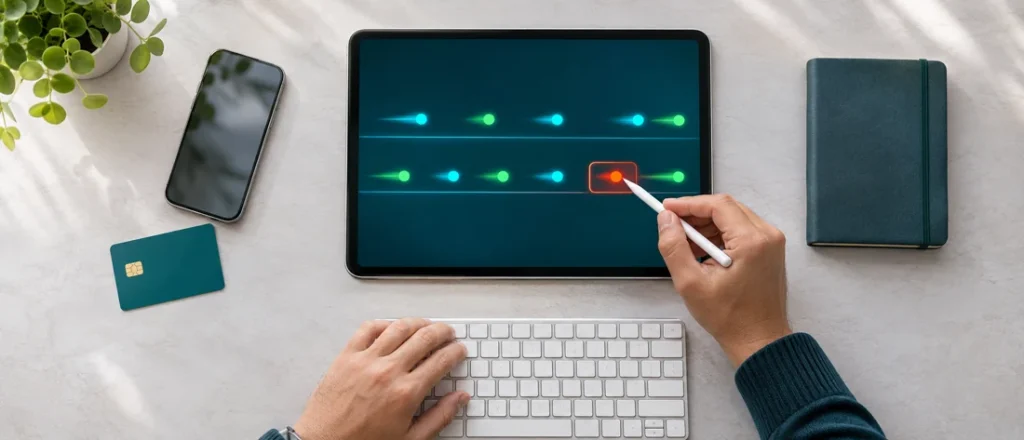
Kafka Streams can support this type of real-time processing by continuously analysing events as they move through Kafka. It supports stateful operations, windowing, joins, aggregations, and event-time processing, which are useful when fraud decisions depend on both current and recent activity.
This article describes how companies can use Kafka Streams to create real-time fraud detection models and what factors should be taken into account before putting such models into production.
What Is Real-Time Fraud Detection?
Real-time fraud detection is a process that analyses transactions made by organizations or users as they occur and detects any suspicious behaviour during the process.
A fraud detection system may examine information such as:
- Transaction amount and frequency.
- Customer or account history.
- Device and location information.
- Recent failed attempts.
- Unusual behavioural patterns.
- Changes from normal spending or usage.
- Known fraud rules or risk indicators.
Its purpose is to identify suspicious activity quickly enough for the business to respond before significant damage occurs. Depending on the level of risk and threat, the system may approve or request additional verification and it may send notification or manual review or block the activity.
What Are Kafka Streams?
Kafka Streams is an open-source distributed streaming platform that is used to build data pipelines, streaming analytics, data integration and applications that process data stored in Apache Kafka.
Kafka carries transactions and customers events, while Kafka Streams processes those events and applies logic needed to identify suspicious activities.
It is particularly helpful for fraud detection because it can maintain information about recent events through state stores and group events into specific time periods using windowing. This allows a fraud system to evaluate a transaction within the context of what happened immediately before any suspicious activity occurs.
Related Post :-
- Data Warehouse Governance – Best Practices, Security & Privacy
- Data Analyst vs Business Analyst vs Data Scientist – Key Differences
How Does Real-Time Fraud Detection Using Kafka Streams Work?
A fraud detection system works using different levels of evaluation in the mean time to give accurate outcomes while the activity is in progress.
1. Capture Events in Real Time
The process starts by collecting events that may be useful for detecting fraud.
These events could come from:
- Payment systems
- Banking applications
- E-commerce platforms
- Customer applications
- Login systems
- Devices or digital channels
The events are published to Kafka topics so that they become available for continuous processing. For example, a transaction event may contain the account ID, transaction amount, merchant, timestamp, and other relevant information. All this data is captured in Kafka.
2. Prepare and Enrich the Data
A single transaction could not offer sufficient details to detect fraud. Therefore, it could be necessary to add extra context to every incoming event, such as customer information, account details, past transactions, device history, or recognized risk flags.
Kafka Streams supports combining these events together, allowing applications to connect incoming events with other information needed for the decision. This creates a broader view of the transaction activity before it reaches the fraud model.
3. Build Real-Time Fraud Features
Fraud models usually depend on features that describe recent behaviour.
Instead of looking only at the current transaction amount, the system may calculate:
- Number of transactions within the last few minutes.
- Total spending during a recent period.
- Number of failed attempts.
- Changes in transaction locations.
- Frequency of activity from the same account or device.
Kafka Streams windowing allows events to be grouped over defined periods so these features can be calculated continuously. These real-time features provide the model with more useful context than the current event alone.
4. Apply Fraud Rules and Model Scoring
When required data and features are made available, the transactions can be evaluated through these approaches:-
- Fraud Rules– It checks for known conditions, such as an unusually high number of transactions within a short period.
- Machine learning models– it calculates risk score based on patterns learned from historical fraud and legitimate transactions.
Kafka Streams acts as the processing layer that continuously prepares the information and connects each new event with the decision logic. The models can be trained both within the Kafka Streams and using historical data through a separated machine learning environment. Then, it can be used for real-time scoring inside the fraud detection workflow.
5. Take Action Based on Risk
The output of the fraud model should lead to a clear action and suggest the right decision.
Transactions can be separated into categories such as:
- Low risk: Continue normal processing.
- Medium risk: Request additional verification.
- High risk: Send for investigation or temporarily stop the transaction.
The result can be written to another Kafka topic and used by payment systems, alerting applications, fraud investigation teams, or other business processes.
A Simple Fraud Detection Example
For instance, consider a customer who normally makes a few small transactions each week. Suddenly, his account generates several transactions within a few hours from a new device, and that transaction is significantly larger than previous ones.
Kafka Streams processes each event as it arrives and maintains the customers recent transactions activity, and combines various events like recent transaction frequencies, new deceive used, transaction amount and previous customer behaviours.
These features are sent through fraud rules or a machine learning model. If the resulting risk score crosses the defined threshold, the transaction can be sent for additional verification or review. Therefore, the decision can happen while the transaction is still being processed rather than hours later.
What Makes Kafka Streams Useful for Fraud Detection?
1. Stateful Processing
Fraud detection works on pattern recognition based on historical activities rather than on transaction history. Kafka Streams can maintain local state for operations such as aggregations and combines, allowing applications to compare current activity with recent behaviours.
2. Time-Based Analysis
Kafka streams reads, records and analyses timestamps that are necessary for fraud detection. A company may need to identify several login attempts, transaction time, or account changes occurring within a short period. Windowing helps analyse these event patterns over defined time intervals.
3. Scalable Event Processing
Transaction volumes grow over time, and as they grow, fraud systems need to process more events without creating delays. Therefore, Kafka Streams uses Kafka’s partitioning model to distribute processing tasks across application instances which allows workloads to scale as event volume increases.
4. Processing Reliability
For fraud detection to work accurately, eliminating duplicate or inconsistent processing problems in financial workflow is a necessary step. Therefore, Kafka Streams ensures configurable processing guarantees, including exactly_once_v2, which can help applications coordinate state updates and output records consistently when configured appropriately.
What Should Businesses Consider Before Building the Model?
Technology alone does not create an effective fraud detection system. Businesses also need to consider:
- Data quality: Poor or incomplete transaction data can produce unreliable risk scores.
- Latency: The complete decision process should be fast enough for the business use case.
- False positives: Blocking too many legitimate transactions can affect customer experience.
- Model monitoring: Fraud patterns change, so model performance should be reviewed regularly.
- Rules and thresholds: Risk thresholds should reflect business requirements rather than remain fixed indefinitely.
- Explainability: Fraud teams should be able to understand why important transactions were flagged.
- System monitoring: Teams should monitor stream delays, failures, model scoring, and downstream actions.
The fraud model should therefore be treated as part of an ongoing operational system rather than a one-time machine learning project.
Related Post:-
- Finance Analytics: How BI Helps in Budgeting, Forecasting & Risk Control
- How to Build a Data Science Portfolio That Gets Hired (Complete Guide)
Conclusion
Every online transaction, payment, purchase, and service needs security to ensure a reliable customer experience, as it contains a large amount of customer information. Organizations are always looking for better platforms for securing this business data, fraud detection systems, and governed data pipelines. Building real-time fraud detection models is one of the solutions they need.
Kafka Streams help firms to build real-time fraud detection models that allows businesses to analyse transactions while activity occurs and respond to suspicious behaviour faster. They can connect incoming events with recent activities, maintain real-time features, apply fraud rules, and process the result to the appropriate business application application instances.
However, the quality of a fraud system depends on reliable data, meaningful features, appropriate threshold, model monitoring, scalable infrastructure, and clear business actions as well as processing all these with faster speed.
So, a well- designed architecture fraud detection model connects all these components so that fraud detection becomes an on-going process that can adapt with the increasing volume and changing fraud patterns of transactions.